Agentic MLOps

Import any open-weight model, fine-tune it on your data, and put it into production — fully hosted, autoscaled, and fast at inference. One platform for any model architecture — language, vision, predictive, or whatever comes next.

<50ms
p50 inference latency
10+
open-weight model families supported
Any
model architecture — not limited to a fixed set of types
How It Works

Model Lifecycle

From checkpoint to production, every model moves through a clearly defined, repeatable evaluation loop — keeping it accurate on the latest data.

Import or select a model

Bring an open-weight checkpoint, or start from a supported base model in the registry.

Evaluate

Evaluation gates score every candidate and block promotion until it passes.

Fine-tune

Retrain with LoRA or a full fine-tune — every run versioned and reproducible.

Deploy

One-click promotion with canary rollout and instant rollback.

Serve

Autoscaled, monitored inference at 42ms p50. Drift or new data kicks off the next loop.

LoRA, QLoRA, and full fine-tuning support
Autoscaling GPU endpoints with cold-start protection
Dynamic batching and KV-cache reuse for throughput
INT8 / INT4 quantization for latency-sensitive workloads
Model registry with lineage and versioned checkpoints
Drift and accuracy monitoring wired to retraining triggers
Capabilities

From open-weight checkpoint to production endpoint

Import any model, retrain on demand

Bring an open-weight checkpoint — or your own architecture — once, then fine-tune it again and again as new data arrives with LoRA or full training. Every run is versioned and reproducible.

Fully managed, fast inference

Autoscaling GPU endpoints with quantization, batching, and caching tuned automatically for whichever the workload needs — latency or throughput.

Evaluated before every release

Each retrained version passes gated evaluation before promotion. Drift and accuracy are tracked continuously to trigger the next loop, while canary rollout and one-click rollback keep a bad version from reaching everyone.

Model Types

Deploy across various modalities

Whatever kind of model your use case needs, it moves through the same import, fine-tune, and serve pipeline.

USE CASE · CLINICAL PII REDACTION

Patient NAMEJohn Michael Carter, DOB DOB03/14/1967, MRN MRN88213045, presented to the ER with chest pain. Contact PHONE(703) 555-0142 and SSN SSN512-33-9087 confirmed for records.
5 PII entities detected·redaction latency 18ms·phi-redact-clinical-v2
Redaction confidence
NAME
97.8%
DOB
94.2%
MRN
99.1%
PHONE
91.5%
SSN
98.6%
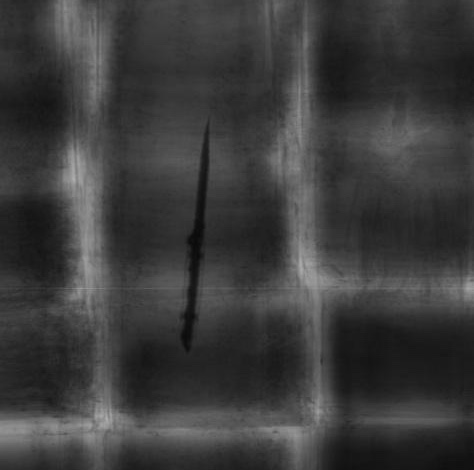
X-ray cargo scan with a concealed sharp object flagged
Sharp Object · 96%
USE CASE · X-RAY CARGO ILLICIT OBJECT DETECTION

Flags contraband before it clears the belt

A vision model trained on X-ray cargo scans localizes concealed items in real time, classifying each finding with a confidence score so screeners can triage instantly.

Detected classSharp Object
Confidence96.2%
Inference time61ms
Use Case · Q3 revenue forecast
today
$2.05M $2.15M $2.28M $2.41M
solid = actuals·dashed = forecast·demand-forecast-v4
Predicted Q3 revenue
$2.41M
+12.4% QoQ
Confidence interval89%
Forecast horizon90 days
Model R²0.94

…and any other architecture your use case calls for — recommendation, ranking, anomaly detection, speech, or a custom model you've already built.

Model Observability

Know the moment a model starts to drift

Every hosted model — whatever it predicts — reports the same core signals, so nothing silently degrades in production.

Data and prediction drift, measured against the training distribution
Accuracy and quality metrics tracked against ground truth as it arrives
Latency, throughput, and GPU cost per model, per endpoint
Automatic alerts and retraining triggers before quality impacts users
DRIFT · demand-forecast WATCH
threshold
Drift score
0.34
Accuracy 7d
91.2%
GPU cost/day
$142
In the Product

The Model Registry & Inference Dashboard

Every model you host with live latency, throughput, and drift in one view.

thinkstack — mlops
cargo-xray-v2
Vision Transformer (ViT-L/14) · fine-tuned on cargo X-ray dataset
endpoint live
Accuracy
97.8%
Latency p50 / p95
42 / 88ms
Cost / 1K inferences
$0.18
Throughput
1,240 img/min
Accuracy · 24h97.8% now
99% target
Latency p50 · 24h42ms now
Fine-tuning losstrain loss 0.184
Recent inference events streaming
cargo-xray-v2 · /detect-object · sharp_object 0.96200 OK · 38ms
cargo-xray-v2 · /detect-object · clear 0.99200 OK · 41ms
cargo-xray-v2 · /detect-object · organic_matter 0.88200 OK · 44ms
cargo-xray-v2 · /detect-object · sharp_object 0.91retried · 112ms

Frequently Asked Questions

Common questions about Agentic MLOps.

What does this do that a model registry doesn't?+
It covers the whole path. Import an open-weight checkpoint or your own architecture, fine-tune it on your data with LoRA or full training, gate it behind an evaluation suite, promote it in one click, and serve it on an autoscaled endpoint. Every run is versioned and reproducible, and the registry keeps lineage per checkpoint.
Are we limited to language models?+
No. Language, vision, and predictive models move through the same import, fine-tune and serve pipeline, as do recommendation, ranking, anomaly detection and speech models, or a custom architecture you've already built. The page's own examples span clinical PII redaction, X-ray cargo screening and revenue forecasting.
Who manages the inference infrastructure?+
ThinkStack does. Endpoints autoscale with cold-start protection, and quantization, dynamic batching and KV-cache reuse are tuned automatically for whatever the workload needs — latency or throughput. INT8 and INT4 quantization are available for latency-sensitive work. No infrastructure work is required to promote a model to a served endpoint.
How do we know a model is still good once it's live?+
Every hosted model reports the same core signals regardless of what it predicts: data and prediction drift measured against the training distribution, accuracy tracked against ground truth as it arrives, and latency, throughput and GPU cost per endpoint. Alerts and retraining triggers fire before quality reaches users.
What stops a bad version reaching everyone?+
Two gates. An evaluation suite blocks promotion until the model passes, and rollout is canary-based with one-click rollback, so a regression reaches a slice rather than the whole endpoint. Model versions and checkpoints are kept in the registry with lineage, so the previous version is always a known artifact.
How do we get a model into production?+
Three steps. Import an open-weight checkpoint of your choosing, or start from a supported base model already in the registry. Fine-tune on your data with LoRA or a full fine-tune, with evaluation gates blocking promotion until it passes. Then one click promotes it to an autoscaled, monitored inference endpoint.